In a SaaS platform, service availability tells only part of what is actually happening. A system can appear operational and still show signs of degradation in the user experience. When an anomaly emerges, knowing that it exists is useful, but to act on it you need to understand where it originates and which components are involved.
This need is where the distinction between Monitoring and Observability comes from. Monitoring checks the state of applications and infrastructure through indicators defined in advance. Observability, instead, makes it possible to reconstruct the internal behavior of the system through the data it produces while running. For those who manage a SaaS, it means having two complementary levels of reading, one dedicated to control and the other to the analysis of causes.
In the SaaS world this reading capability carries particular weight, because every digital experience depends on a network of services that must communicate with one another. Even a single operation visible to the user can pass through several layers of the application before being completed. If one of these steps slows down or generates an error, the effect can be immediately reflected in the quality of the service. For the provider, this means having to quickly identify the origin of the anomaly, limit the impact on users, and give the technical team useful information to act. The greater the visibility into what happens inside the platform, the shorter the distance between the first signal and identifying its cause.
You might also be interested in:
XLA vs SLA: experience-oriented metrics that are transforming IT support
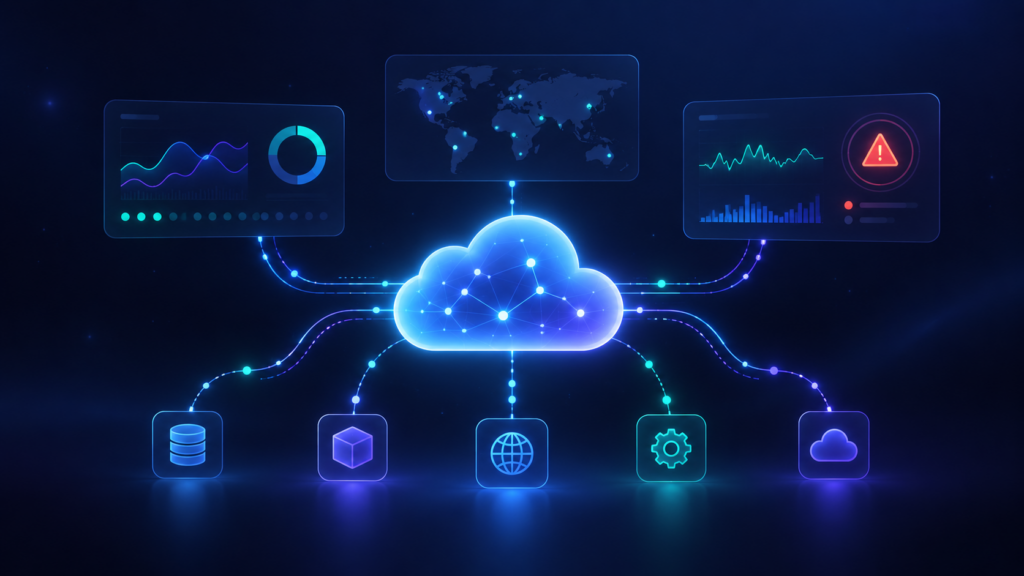
Monitoring starts from what we already know we need to observe
Every monitoring activity begins with the definition of the parameters to keep under control. The team decides which values to observe and which thresholds require attention.
If an indicator exceeds the expected limit, an alert is generated. The team thus receives an immediate signal and can check the state of the service involved.
Monitoring works particularly well when the behavior to detect is already known. It allows performance to be tracked continuously and enables a quick reaction to the most significant variations.
When the origin of the anomaly is not obvious, however, the recorded value alone can leave several questions open.
Observability reconstructs what happens behind the signal
It is at this stage that observability takes on a different role.
Suppose a platform function starts taking longer to complete a request. The latency data shows the change, while analyzing the signals produced by the system makes it possible to follow its path.
The team can thus identify the point where the delay concentrates and check what was happening at that moment.
This makes it possible to investigate even behaviors that had not been anticipated when dashboards and alerts were configured.
Metrics, logs and traces show different perspectives
To reconstruct the behavior of a SaaS application, you need information coming from different levels.
Metrics help identify variations in performance and in the state of the services.
Logs document the events generated while activities run and make it possible to look more closely at what happened in a specific step.
Traces, on the other hand, follow a request along its path across the services involved.
The value emerges when this information is connected. A variation detected in the metrics can be associated with an event recorded in the logs and then located through the trace of the request concerned.
Dependencies make finding the cause less immediate
A SaaS platform rarely works as a single block.
The features available to users often depend on several services that communicate with one another. Added to these are external resources and integrations that take part in carrying out certain operations.
As a result, the point where the user perceives the problem can be far from its technical origin.
Observability makes it possible to follow these relationships and gives the team a broader reading of the application’s behavior. This reduces the number of checks needed to understand where to focus the analysis.
More alerts do not necessarily mean more visibility
A single problem can generate several notifications within the infrastructure.
If each event is analyzed in isolation, the team risks devoting resources to the same cause multiple times. Moreover, a high volume of notifications makes it harder to quickly determine which ones require immediate attention.
Correlating signals helps recognize when multiple alerts belong to the same incident.
The quality of observation therefore also depends on the ability to create relationships between the available information and to reduce noise during analysis.
The real value emerges during incident management
The difference between receiving an alert and understanding its origin becomes particularly clear during an incident.
When the team already has the information needed to locate the problem, it can start management activities from a more complete basis. This reduces the work spent on preliminary investigation and increases the speed at which the case can be routed to the right people.
This is where the connection with IT Service Management becomes particularly relevant.
The data coming from technical tools can accompany the incident within the management workflow. Operators therefore have access to the information gathered during analysis without having to reconstruct every step manually.
From signal to action
Monitoring and Observability cover different stages of the same journey.
The first offers a continuous view of the status of the services and signals when something moves away from the expected values. The second makes it possible to look more deeply at that signal and reconstruct what happens inside the application.
For a SaaS, the advantage lies in the possibility of shortening the distance between the appearance of a problem and identifying its origin.
When this information also enters Service Management processes, the next step becomes smoother. The incident can be assigned and followed within the same operational flow.
With Deepser, alerts coming from monitoring systems can be integrated into Service Management workflows and handled directly as incidents. Automations support task assignment, while SLAs allow the process to be tracked through to resolution.
Try our free demo and discover how we can support your company.